
When DeepSeek Turned the AI World Upside Down
- By Paul Mah
- February 13, 2025
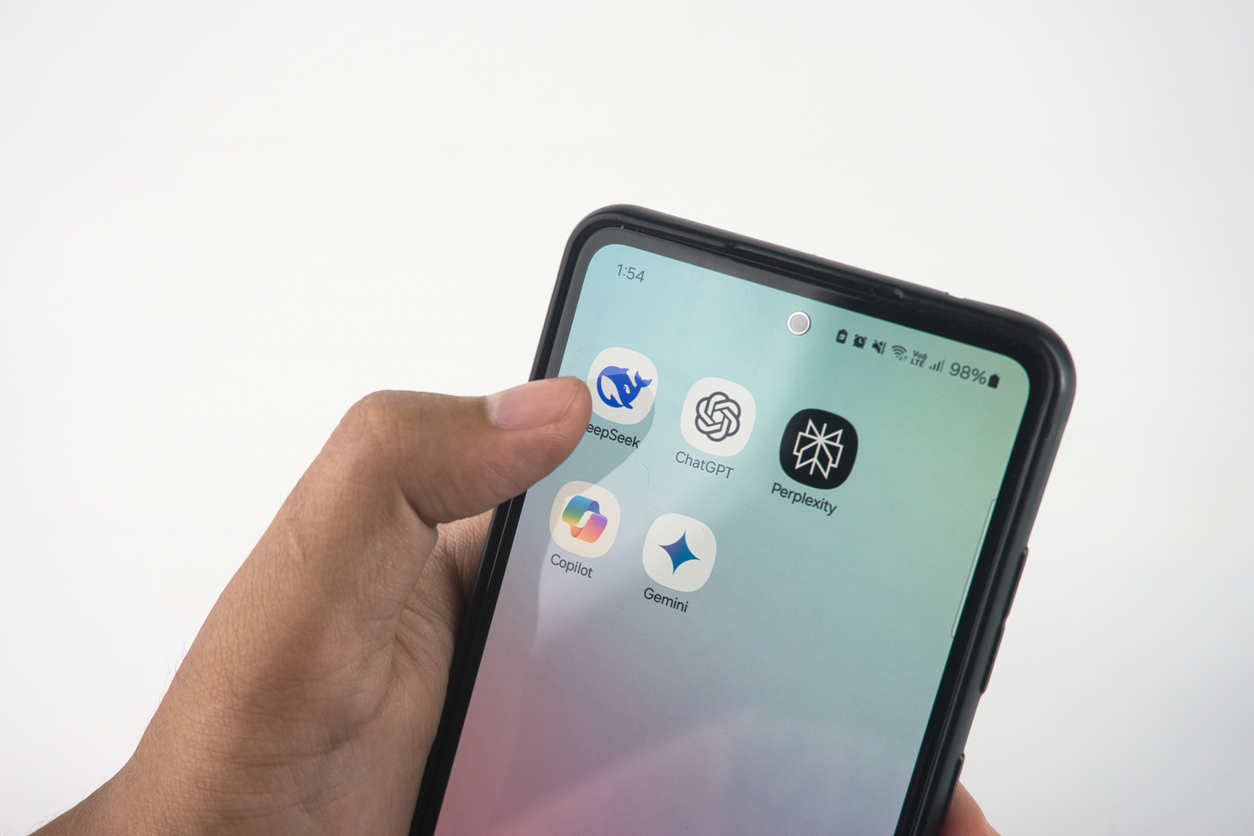 DeepSeek's meteoric rise in the AI industry took everyone by surprise, including many AI experts. So, what exactly did this relatively young team do to outpace far more established competitors?
Founded in 2023 by former hedge fund manager Liang Wenfeng, DeepSeek adopted an unconventional team-building strategy. They prioritized raw talent over industry experience resulted in a diverse team not bound by traditional methods where 80% of technical roles were filled by recent graduates or researchers with less than two years of work experience.
This focus on fresh talent, combined with the challenges the team faced, spurred them to innovate rapidly and develop groundbreaking solutions that disrupted the market.
A different approach
Restricted to underpowered China-only Nvidia H800 GPUs, the DeepSeek team worked hard to optimize the limited resources they had. To begin with, they opted for 8-bit floating point numbers (FP8) instead of the more common 32-bit (FP32) numbers used in AI applications. Since FP8 implementations struggle with precision loss, the team came up with a novel approach to ensure accuracy.
The DeepSeek team created a new system to break numbers into small tiles and blocks to switch between FP8 and FP32. This allowed them to efficiently manage computational resources without sacrificing performance. The result? An incredible 75% reduction in memory usage.
To eke more performance from their bandwidth-limited GPUs, the team implemented assembly-like programming (Nvidia PTX) instead of relying solely on the CUDA API. Using PTX, they made optimizations to GPUs for efficiency and even reassigned some cores for server communication. By using data compression for inter-GPU communication, the team overcame the limited bandwidth to dramatically improve GPU performance.
Innovation as the driving force
Beyond enhancing the efficiency of their hardware, DeepSeek's team also pioneered new neural network architectures that utilized fewer parameters without compromising accuracy. Moreover, DeepSeek was also trained using reinforcement learning with minimum reliance on supervised fine-tuning commonly used to train AI models.
The use of automated feedback instead of human feedback accelerated the training process and reduced the potential for human bias. By reducing time-consuming human intervention, this reduced cost significantly and maintained high model accuracy.
Another example would be the Mixture-of-Experts (MoE) architecture used by DeepSeek. Though MoE isn't new – OpenAI uses it, the DeepSeek team made architectural innovations and succeeded in implementing it at a far more granular level than the 16 that GPT-4 is believed to use.
With smaller, highly specialized experts to handle specific tasks, this led to more efficient processing and improved model performance. Ultimately, this fine-tuning of the MoE approach allowed DeepSeek to achieve state-of-the-art results while utilizing fewer computational resources than their competitors.
The results speak for themselves: the DeepSeek model activates only 37 billion parameters out of its total 671 billion parameters for any given task. The result is similar performance at a fraction of the compute and is reflected in the cost that put the DeepSeek R1 model at just 4% of the cost of OpenAI's o1 model.
Despite limited resources, DeepSeek's innovative approaches to hardware optimization and neural architecture design enabled remarkable AI performance while drastically reducing computational costs.
Image credit: iStock/Galeh Kholis Pambudi




Paul Mah
Paul Mah is the editor of DSAITrends, where he report on the latest developments in data science and AI. A former system administrator, programmer, and IT lecturer, he enjoys writing both code and prose.