
Tangled Data Pipelines? Here’s How IBM Wants to Fix Them.
- By Winston Thomas
- March 25, 2026
What’s the number that will make every CDO pause while having their much-needed morning coffee? IBM cites 43% in its Data Integration eBook. It’s the share of organizations that believe data is changing faster than they can keep up with, and is a number found in IDC’s August 2024 Global Data Validation Survey.
It means CDOs are a bit like a chef whose ingredients keep multiplying, except the menu is now powered by AI, the investors are watching, and the kitchen needs a serious upgrade. And no, another stove (or ETL tool) won’t be enough.
The pipeline paradox
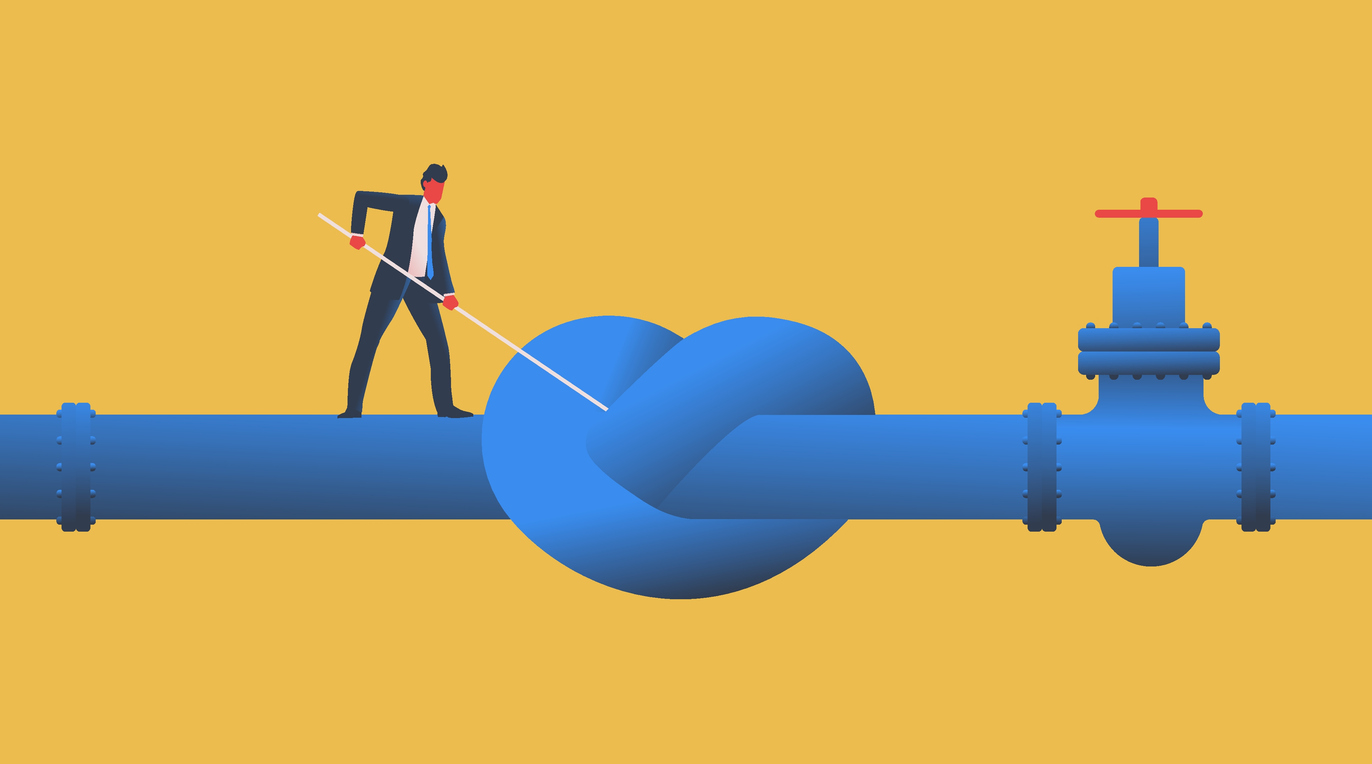
IBM has a useful analogy for what a data pipeline should do: think of it like an oil pipeline — carrying crude from extraction sites, refining it, and distributing the finished product to consumers. Data pipelines should do the same: extract raw data from different sources, process it, and deliver it ready for business and AI. The problem is that for most enterprises, the pipeline is less a well-engineered system and more a tangle of garden hoses, duct tape, and irrational optimism.
For the past decade, organizations have been on a binge. Every new data trend, from cloud warehouses and data lakes to lakehouses and real-time streaming, required new tools. New tools meant new teams, new skills, new contracts, and eventually, new chaos. Today, 70% of organizations run more than one data integration tool, and half juggle at least three, according to IBM’s own research. It means organizations do not own a stack; they have a Jenga tower.
The downstream effects are well-documented. IBM identifies duplicated pipelines, overlapping skills, escalating cloud consumption, prolonged delivery cycles, and a widening governance gap due to inconsistent metadata and controls across tools. There’s even a name for the accumulated wreckage: “pipeline technical debt.” Each time a new architecture emerges, organizations sometimes have no choice but to rewrite their pipelines from scratch. Every migration costs millions of dollars and person-years of rework.
As the number of pipelines scales, visibility into resource consumption disappears. Thousands of pipelines running across different environments and schedules can lead to unexpected cloud bills and runaway egress costs. IBM calls this the FinOps problem hiding inside your data stack.
Over time, too many custom pipelines per domain can become unmanageable. These lead to frequent failures due to schema drift, conflicting data quality metrics across tools, slow onboarding of new data sources, manual governance workarounds, and a growing gap between data availability and business expectations. These aren’t isolated or hypothetical cases; for most large enterprises, they’re Tuesday.
The result: data engineers spend more time maintaining pipelines than building new ones. That’s talent budget going into patching a leaking roof instead of designing a new building. No wonder 68% of surveyed CEOs say integrated enterprise-wide data architecture is critical to enabling cross-functional collaboration and driving innovation. Yet, in reality, most organizations are nowhere near it.
AI’s open secret
Every organization right now is racing to deploy AI — generative AI, agentic AI, RAG-based applications, you name it. And every single one of those initiatives depends on data pipelines that work. According to IBM, 95% of IT leaders report that integration issues are impeding AI adoption. In a parallel finding, IDC’s 2025 MarketScape found that 95% of AI projects fail to deliver on their promises due to poor data quality.
You can have the world’s most sophisticated LLM. If the data feeding it is stale, siloed, or ungoverned, you’ve just built a very expensive hallucination machine.
IBM argues that the solution isn’t yet another point tool. It’s a paradigm shift. Their answer is watsonx.data integration, launched in June 2025: a unified control plane that handles batch ETL/ELT, real-time streaming, change data capture, replication, and unstructured data — all from a single pane of glass, underpinned by AI-powered automation and built-in observability.
IBM defines this as a “data integration and intelligence fabric.” It is not a product category, but an architectural approach. One that uses active metadata, AI-driven automation, and open integration services to connect and govern data across distributed hybrid and multi-cloud environments in real time, without forcing wholesale data movement with watsonx.data intelligence. The non-negotiables, as IBM frames them for CDOs: multi-style integration in a single operating model, native handling of unstructured data at scale, end-to-end lineage and data quality monitoring, policy-driven governance enforced everywhere data is used, and a hybrid-by-design deployment model that runs on-premises or across clouds while remaining open and interoperable.
What CDOs should actually be excited about
The pitch to CDOs goes well beyond consolidation. IBM frames watsonx.data integration as "AI for data, and data for AI." It is a two-way value proposition that’s hard to argue with.
On the "AI for data" side: AI-powered agents can now interpret natural language requests and automatically generate and adapt integration pipelines with no coding required. Business teams can use their domain expertise to design pipelines, while data engineers are freed from low-level pipeline coding and constant firefighting. In practice, IBM views this as a shift in the dataops operating model: engineers move from stitching tools together to curating reusable data products, defining policy, handling exceptions, and taking ownership of outcomes. The new skills that matter aren’t tool-specific scripting — they’re prompt-driven pipeline design, metadata stewardship, and AI governance.
Data drift gets detected automatically using active metadata. Code quality checks and CI/CD pipelines run without human babysitting. IBM also brings dataops discipline to the table, treating pipelines as code, implementing version control, conducting unit testing, and deploying continuous data observability to proactively monitor pipeline health and catch issues before they reach end users. In IBM’s own Chief Data Office — which manages nearly 4,000 data pipelines — implementing data observability through watsonx.data integration produced an estimated 85% reduction in manual monitoring and troubleshooting in a pilot.
On the "data for AI" side, the most underappreciated capability is unstructured data integration. Right now, 90% of enterprise data is unstructured, from documents, PDFs, and emails to logs and images. Only 1% of it is currently used in generative AI. IBM’s unstructured data integration capability allows teams to build pipelines that ingest, transform, and process this content at scale, automatically chunking, embedding, and populating vector stores for RAG-based applications.
But IBM is quick to flag what CDOs consistently miss about this: the real complexity isn’t ingestion but governance over the full lifecycle. IBM sees unstructured data requiring lineage, quality checks, access controls, and automatic re-embedding triggers whenever source content changes. Without that, vector stores quietly become stale, non-compliant, or untrustworthy. Sensitive data must be detected and masked before embedding. Business context must be captured as metadata.
Skip any of the above, and your RAG application becomes a compliance liability dressed up as an innovation story.
The architecture is the strategy
What makes IBM’s approach strategically coherent (and not just tactically) is its architectural philosophy. Watsonx.data integration decouples the pipeline design plane from the underlying storage architecture and execution engines. It means you build a pipeline once, and it doesn’t break every time the industry invents a new storage paradigm. Data teams can build pipelines once and deploy them anywhere — with portability across hybrid cloud and diverse runtime environments.
The approach also directly addresses the FinOps dimension. By processing data where it resides, rather than moving it unnecessarily, organizations can minimize egress costs. Flexible runtime options let pipelines adapt to workload demands and dynamically optimize for cost, performance, and compliance, giving CDOs visibility into resource consumption that has historically been a major blind spot in data operations.
Gartner appears to agree with the broader direction. According to Gartner’s Magic Quadrant for Data Integration Tools (December 2024), as cited in IBM’s watsonx.data integration ebook, AI assistants and AI-enhanced workflows incorporated into data integration tools will reduce manual intervention by 60% and enable self-service data management by 2027. IBM was named a Leader in both the 2025 Gartner Magic Quadrant for Data Integration Tools — for the 20th consecutive year. And the 2025 IDC MarketScape for Worldwide Data Integration Software Platforms, recognition that its strategy is resonating beyond the marketing deck.
IBM also addresses the skills gap head-on. The platform offers no-code, low-code, and code-first interfaces, including a new Python SDK for developers who prefer to treat pipelines as software. The goal is to democratize pipeline creation without dumbing it down. Whether you’re a seasoned data engineer or a domain expert with zero scripting experience, the system meets you where you are.
The honest caveat
None of this is simple to implement. Migrating away from entrenched tool sprawl is an organizational challenge as much as a technical one. And while IBM’s unified control plane is compelling, CDOs should stress-test vendor claims against their own hybrid and multi-cloud environments, which rarely look as clean as architecture diagrams suggest.
That said, the 63% of use cases that need to process data within minutes to be useful — per IDC — can’t afford to wait for the next incremental patch to their legacy stack. Neither can the CDOs who’ve been promised that AI will transform their business, only to discover their pipelines won’t cooperate.
The data integration status quo isn’t just inefficient. In the AI era, it’s a competitive disadvantage measured in quarters, not years. IBM is betting that enterprises are finally ready to stop duct-taping their plumbing and build something that lasts.
For CDOs who’ve spent the past decade managing the chaos: the paradigm shift is overdue. The pipelines you build next should be ones you don’t have to rebuild in three years.
Image credit: iStockphoto/Moor Studio
Stay ahead with CDO Nexus
Join an exclusive community of CDOs and data leaders
- Access curated trends and thought leadership from IBM and industry experts.
- Participate in private roundtables and webinars to solve regional CDO challenges.
- Connect with a network of like-minded leaders navigating the same data landscape.


Winston Thomas
Winston Thomas is the editor-in-chief of CDOTrends. He likes to piece together the weird and wondering tech puzzle for readers and identify groundbreaking business models led by tech while waiting for the singularity.